opal_docs
OPAL (Observational PFAS Access Portal)
(release v1.0)
Documentation Overview
Introduction
Purpose of this document is to provide an overview of documentation for OPAL (Observational PFAS Access Portal). This includes the data model, the steps taken to ingest and make data available in the PFAS Observational Data Access Tool, information about standing up the tool, as well as eventual pointers to scripts and code related to paper analyses.
Use https://pfas-app-prod.renci.unc.edu/ to access the data portal directly.
Documentation for frontend, as well as standing up OPAL frontend, can be found in the following Github repository (https://github.com/RENCI/opal-frontend).
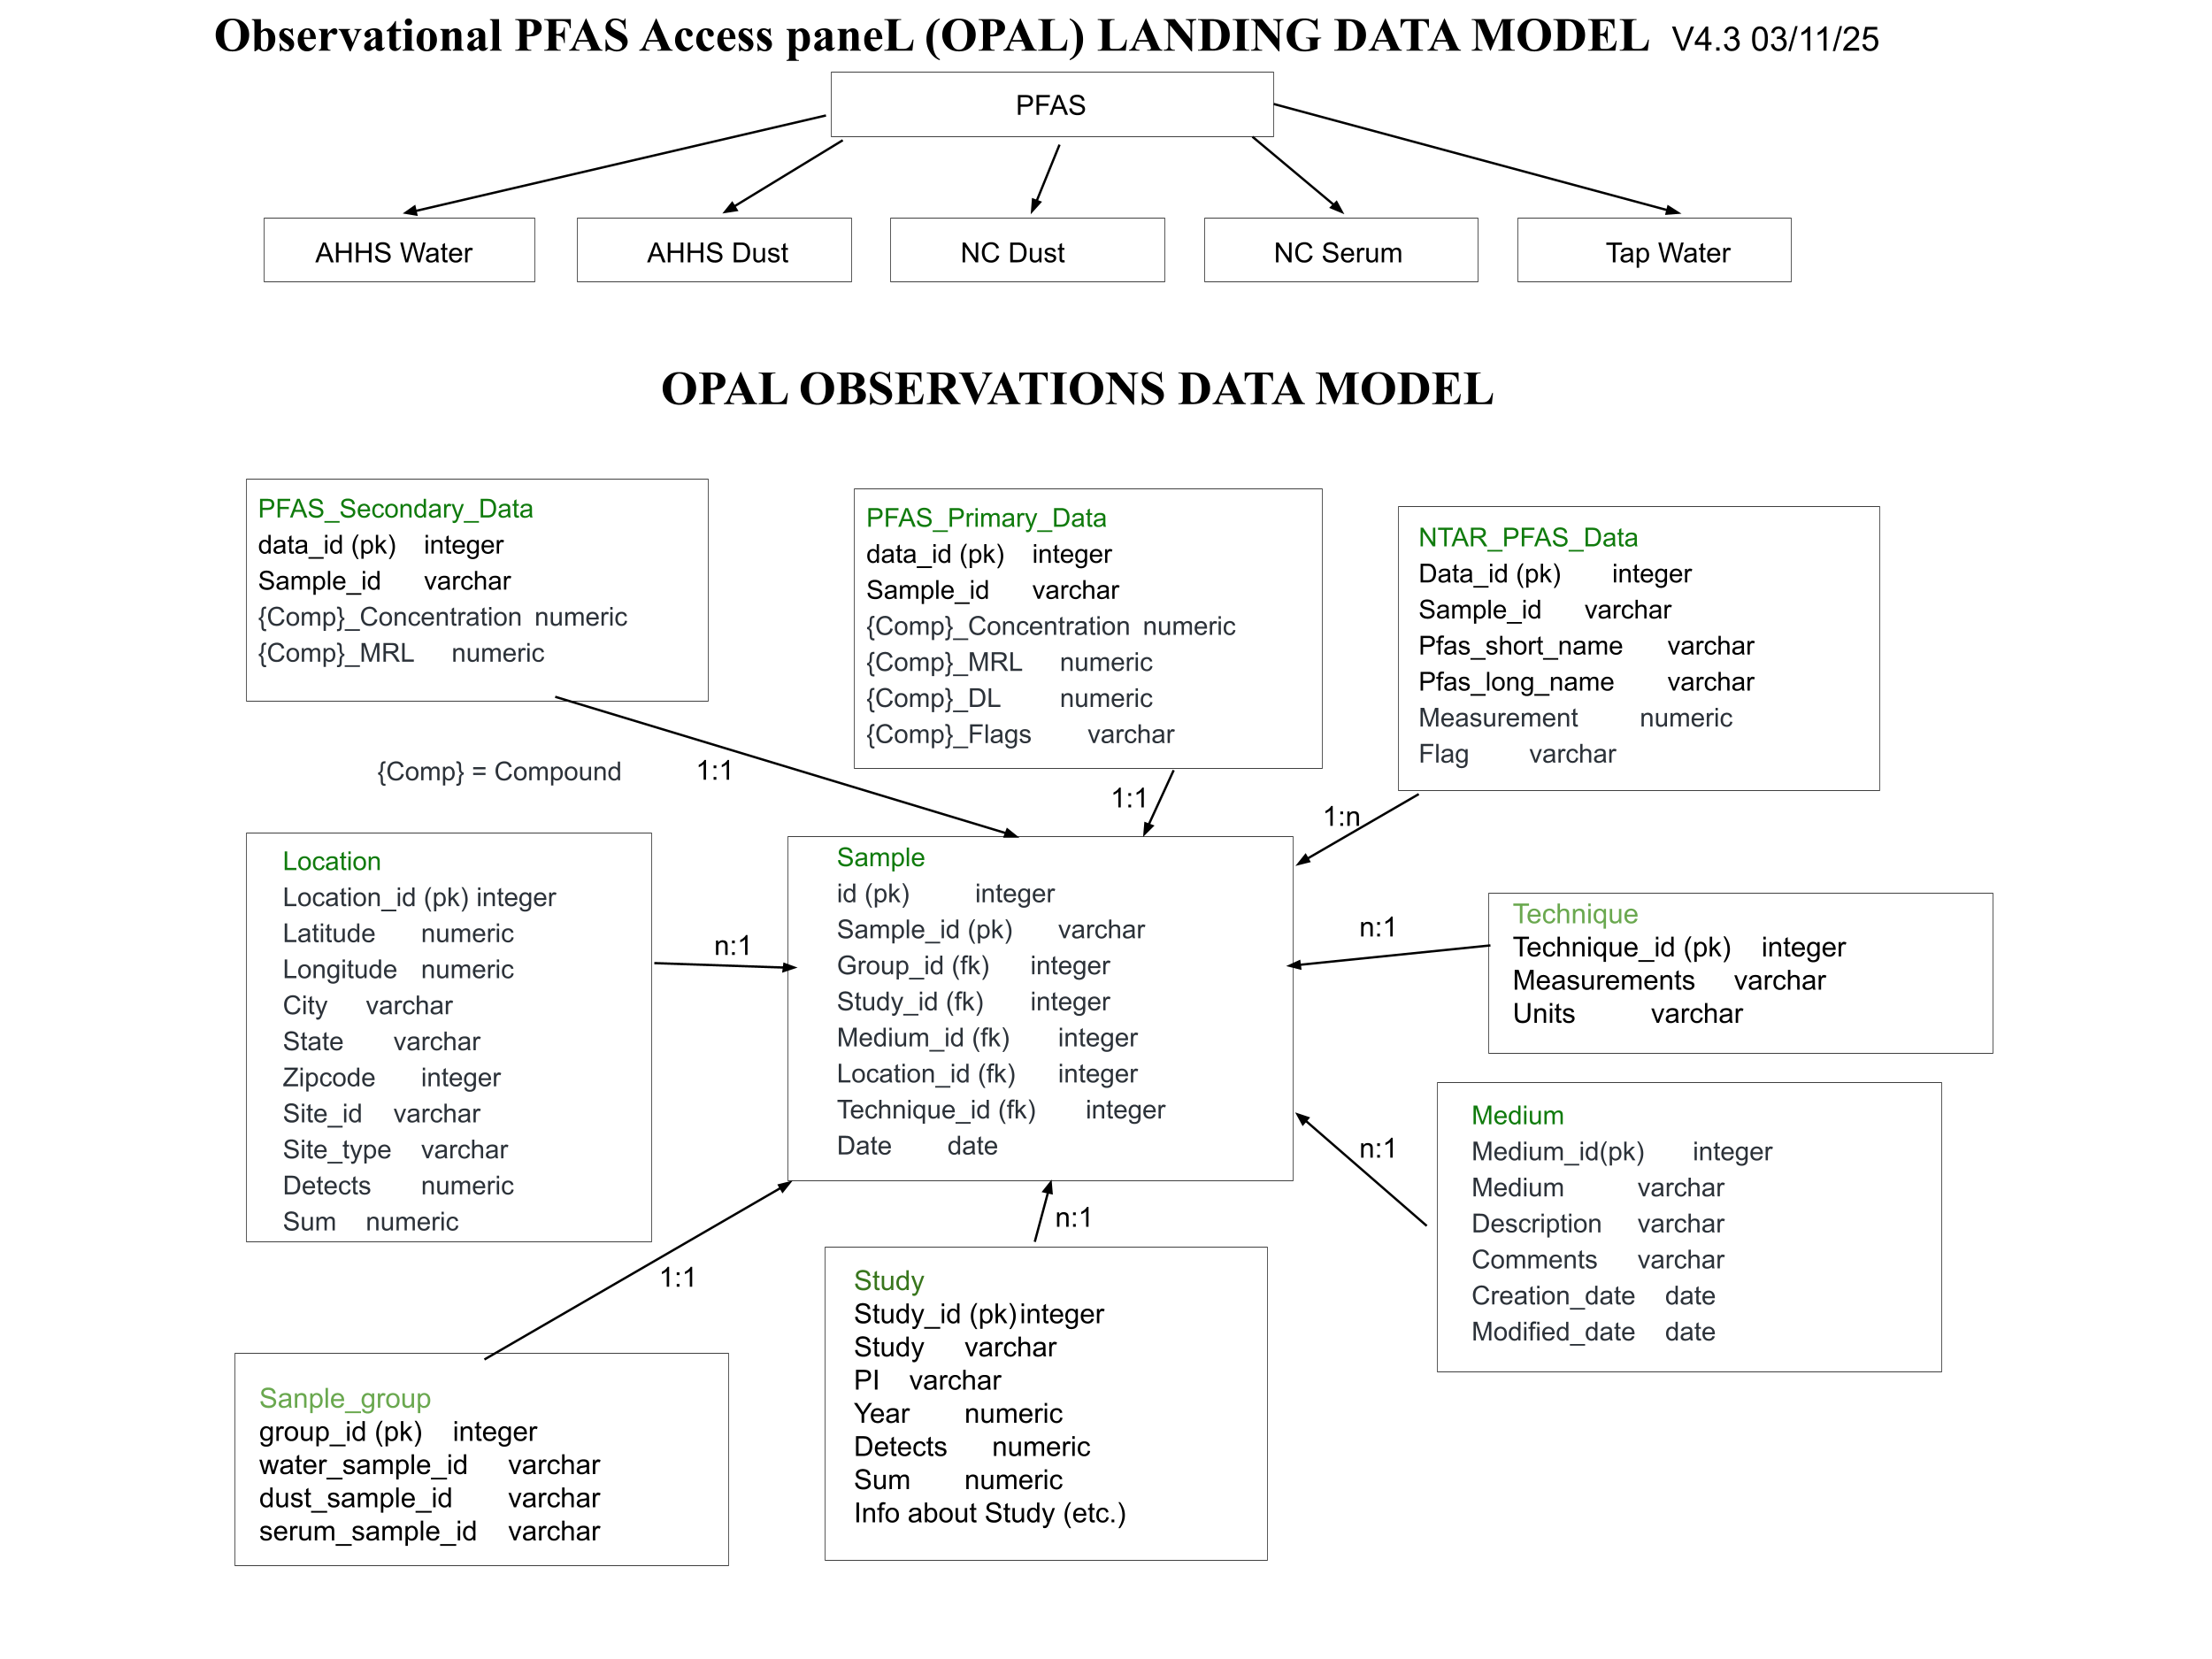
PFAS Observations Data Model
The PFAS Observations Data Model is based on the Observational Data Model 2 (ODM2) and consists of two elements. The first element is the landing data model. This might be termed the pre-database ingest stage of data ingest. Pre-processed files are provided for the Data Landing stage. More information on workflow can be found in the Data Processing Flow section below. The second element is the more detailed data model for the relational database that provides data to the front-end client.
For more information on ODM2 please consult https://www.odm2.org.
Data Processing Flow
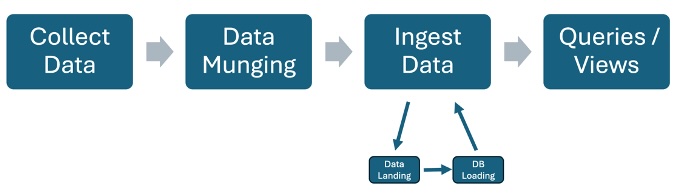
The basic data processing flow is diagrammed below and consists of the following steps:
- Raw data are received and working copies made of the files.
- Initial processing, aka Data Munging, is conducted using the working copies. (See Initial Data File Processing, aka Data Munging section below for more information)
- After initial processing, the data files are staged for the Data Landing.
- After staging, scripts are used to load the data into the PFAS Observations.
- Queries and data views are developed to support front-end client calls.
Initial Data File Processing, aka Data Munging
To view a detailed description of the steps taken as part of initial data processing, please consult the following file: Data_Processing_Steps_Bin.pdf.
Stand-alone R code is accessible in PFAS_Data_Processing.R
For data in V1 of OPAL, input data files and post-processed data files are as follows:
| File From EPA | Processed File for Data Landing (Initial Ingest) |
|---|---|
| AHHS_Dust_DataCleaned_231020.nmd.csv | AHHS_Dust_DataCleaned_231020_nmd_Column.csv |
| AHHS_Water_DataCleaned_231020_nmd.csv | AHHS_Water_DataCleaned_231020_nmd_Column.csv |
| AHHSNontargetedDatasetWater.xlsx | AHHSNontargetedDatasetWater_Column.csv |
| NCSDust_output.csv | NCSDust_output_Column.csv |
| NCSSerum_output.csv + NCS_Serum_Dust_crosswalk_share.csv | NCSSerum_output_Column_Corrected_SampleID.csv |
Data Ingest File Templates
The processed files for Data Landing stage can be used as templates for future data assimilation. Use the file that most closely aligns with your data. See table below.
| Template File for Data Landing (Initial Ingest) |
|---|
| Template_AHHS_Dust_DataCleaned_Column.xlsx |
| Template_AHHS_Water_DataCleaned_Column.xlsx |
| Template_AHHSNontargetedDatasetWater_Column.xlsx |
| NCSDust_output_Column.xlsx |
| NCSSerum_output_Column_Corrected_SampleID.xlsx |
Data Dictionary
A data dictionary describing the relevant attributes of OPAL V1 will be available shortly.
Standing Up OPAL v1
Documentation for database ingest and processing, as well as standing up OPAL va, can be found in the following Github repository (https://github.com/RENCI/opal-backend).
Database Backups and Data Integrity
To maintain data integrity and security, regular backups are made of the database. For more information see details in Github repository reference in previous section.
Additional Scripts and Programs for Processing or Analysis
As additional processing, analytical, or other relevant scripts and programs are developed (e.g. for papers in development) they will be made available as appropriate.
Scripts for exploratory analysis, such as R code, are available on request and are being stored in the project MS Teams space.
Acknowledgements
This was developed under funding from the U.S. EPA under Contract 68HERD21A0002 Task Order 68HERH23F0157 to the University of North Carolina at Chapel Hill by the UNC Institute for the Environment (UNC-IE), Renaissance Computing Institute (RENCI) and the School of Information and Library Science (SILS).